2.2 Observational Studies and Experiments
Section Overview
- Interactive 2.2.1 - Factors & Levels
- Interactive 2.2.2 - Eliminating Lurk. Vars
- Gallery 2.2.1 - More Lurk. Var. Elimination
- Gallery 2.2.2 - Different Experim. Designs
- Example 2.2.1
- Pop Quiz 2.2.1
Introduction to Experiments
You might hear the words “observe” and “experiment” in the same sentence. However, there is a difference between observational studies and experiments. Observational studies aim to collect data on individuals as they are. Experiments, which will be the focus of this section, aim to administer treatments to some aspect of the individuals (quantified as the explanatory variable). These individuals are called experimental units, or subjects if human. Then their reaction, quantified as the response variable, is measured.
When there are multiple explanatory variables in an experiment, each one is called a factor. A specific value of a factor is called a level. When you combine levels, you get different treatments. A representation of this can be found in Interactive 2.2.1, where an experiment was conducted to see how types of breakfast food and hours of sleep a person gets the night before affect test performance.
Interactive 2.2.1 Factors and Levels in an Experiment
Frame 1 of 4
Hours of Sleep: 5, 8, 12. Type of Breakfast: Protein, Carb. Treatments: 1, 2, 3 in the Protein row and 4, 5, 6 in the Carb row. Callouts: Factor, Level, Treatments. Open full-size image S0160Frame 2 of 4
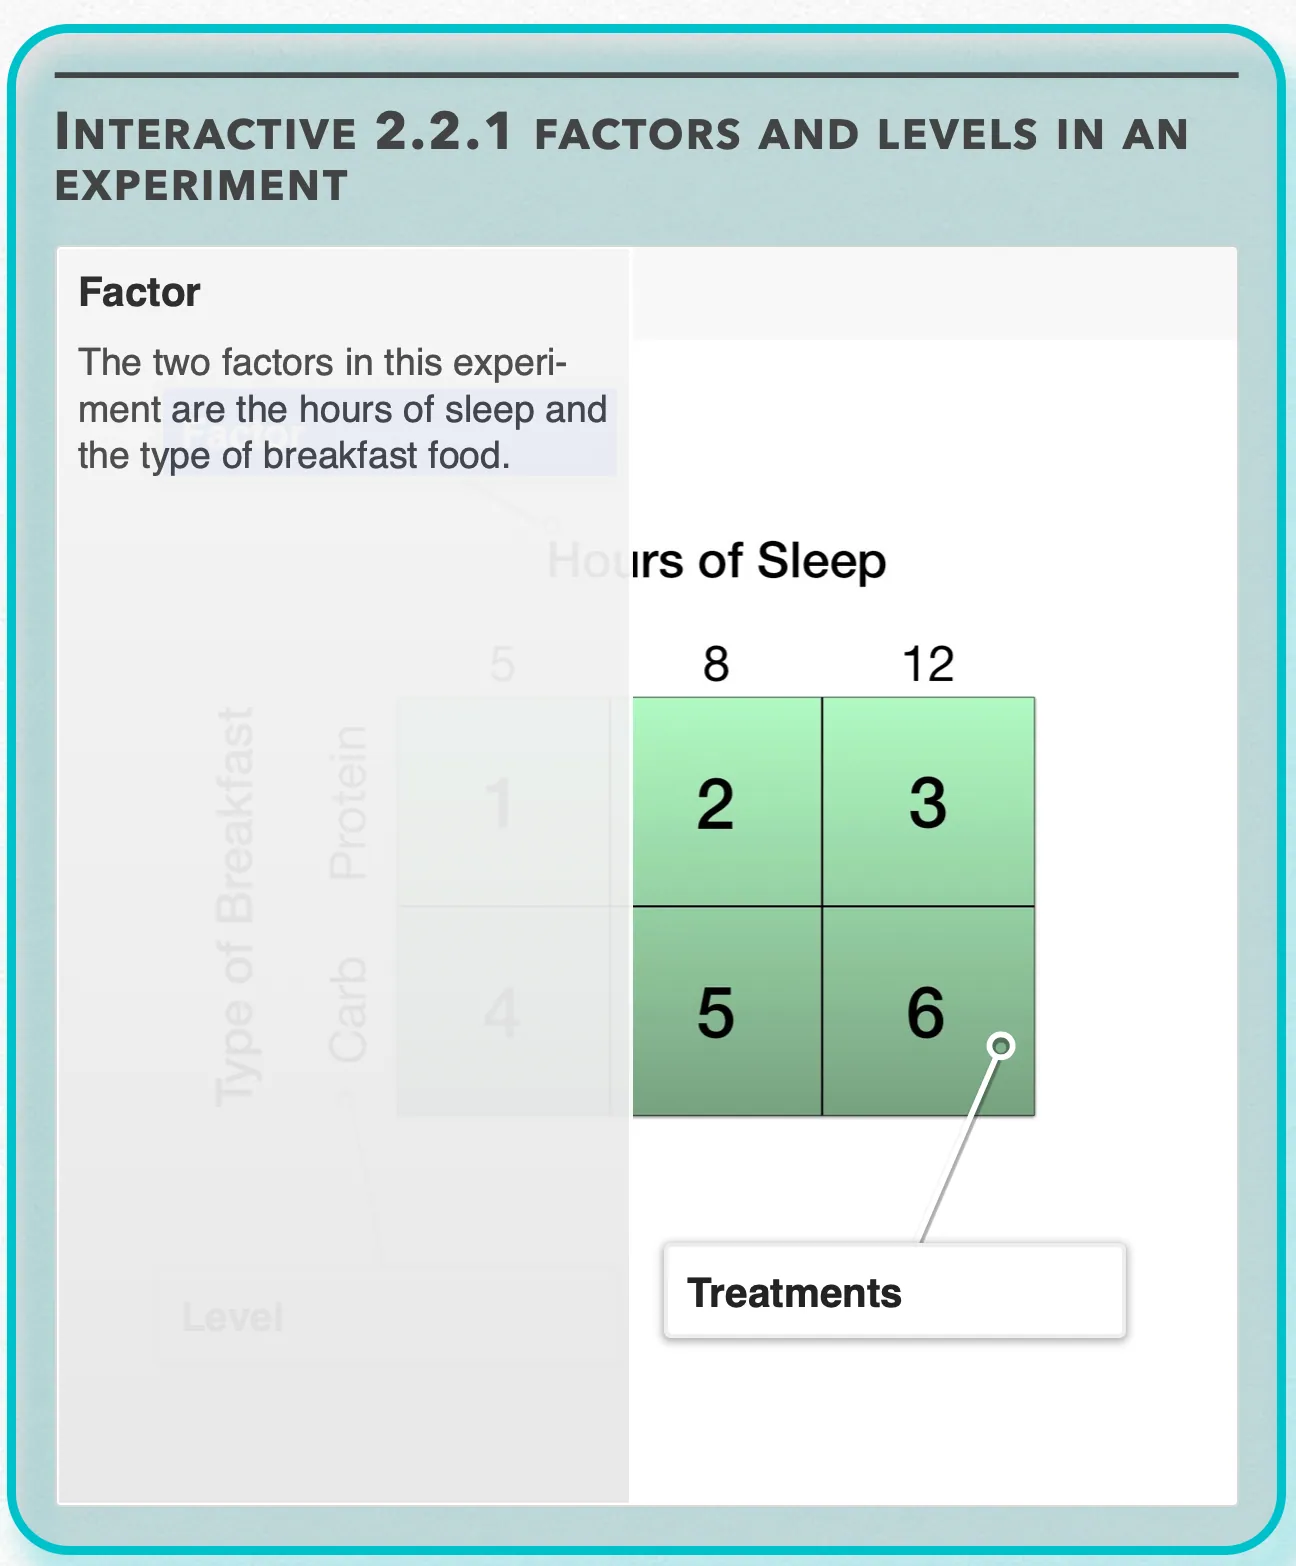
Factor — The two factors in this experiment are the hours of sleep and the type of breakfast food. Open full-size image S0161Frame 3 of 4
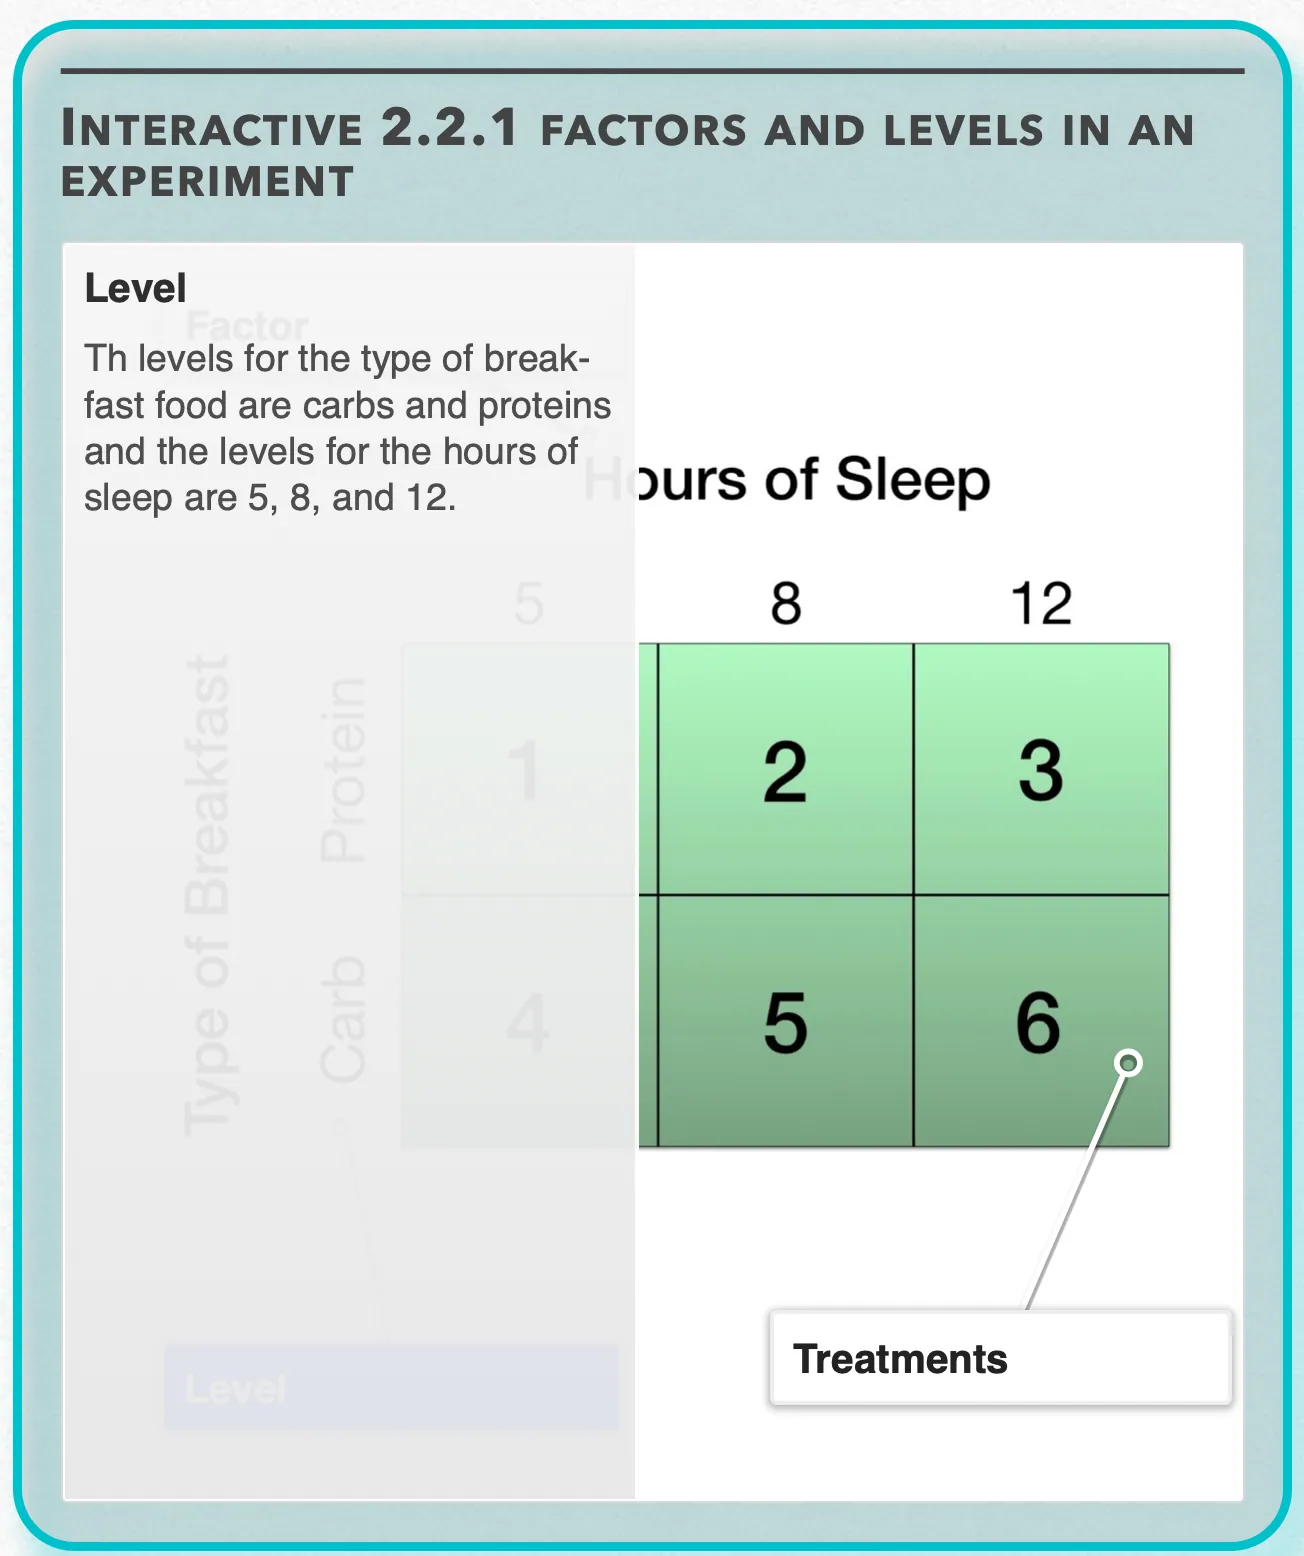
Level — The levels for the type of breakfast food are carbs and proteins and the levels for the hours of sleep are 5, 8, and 12. Open full-size image S0162Frame 4 of 4
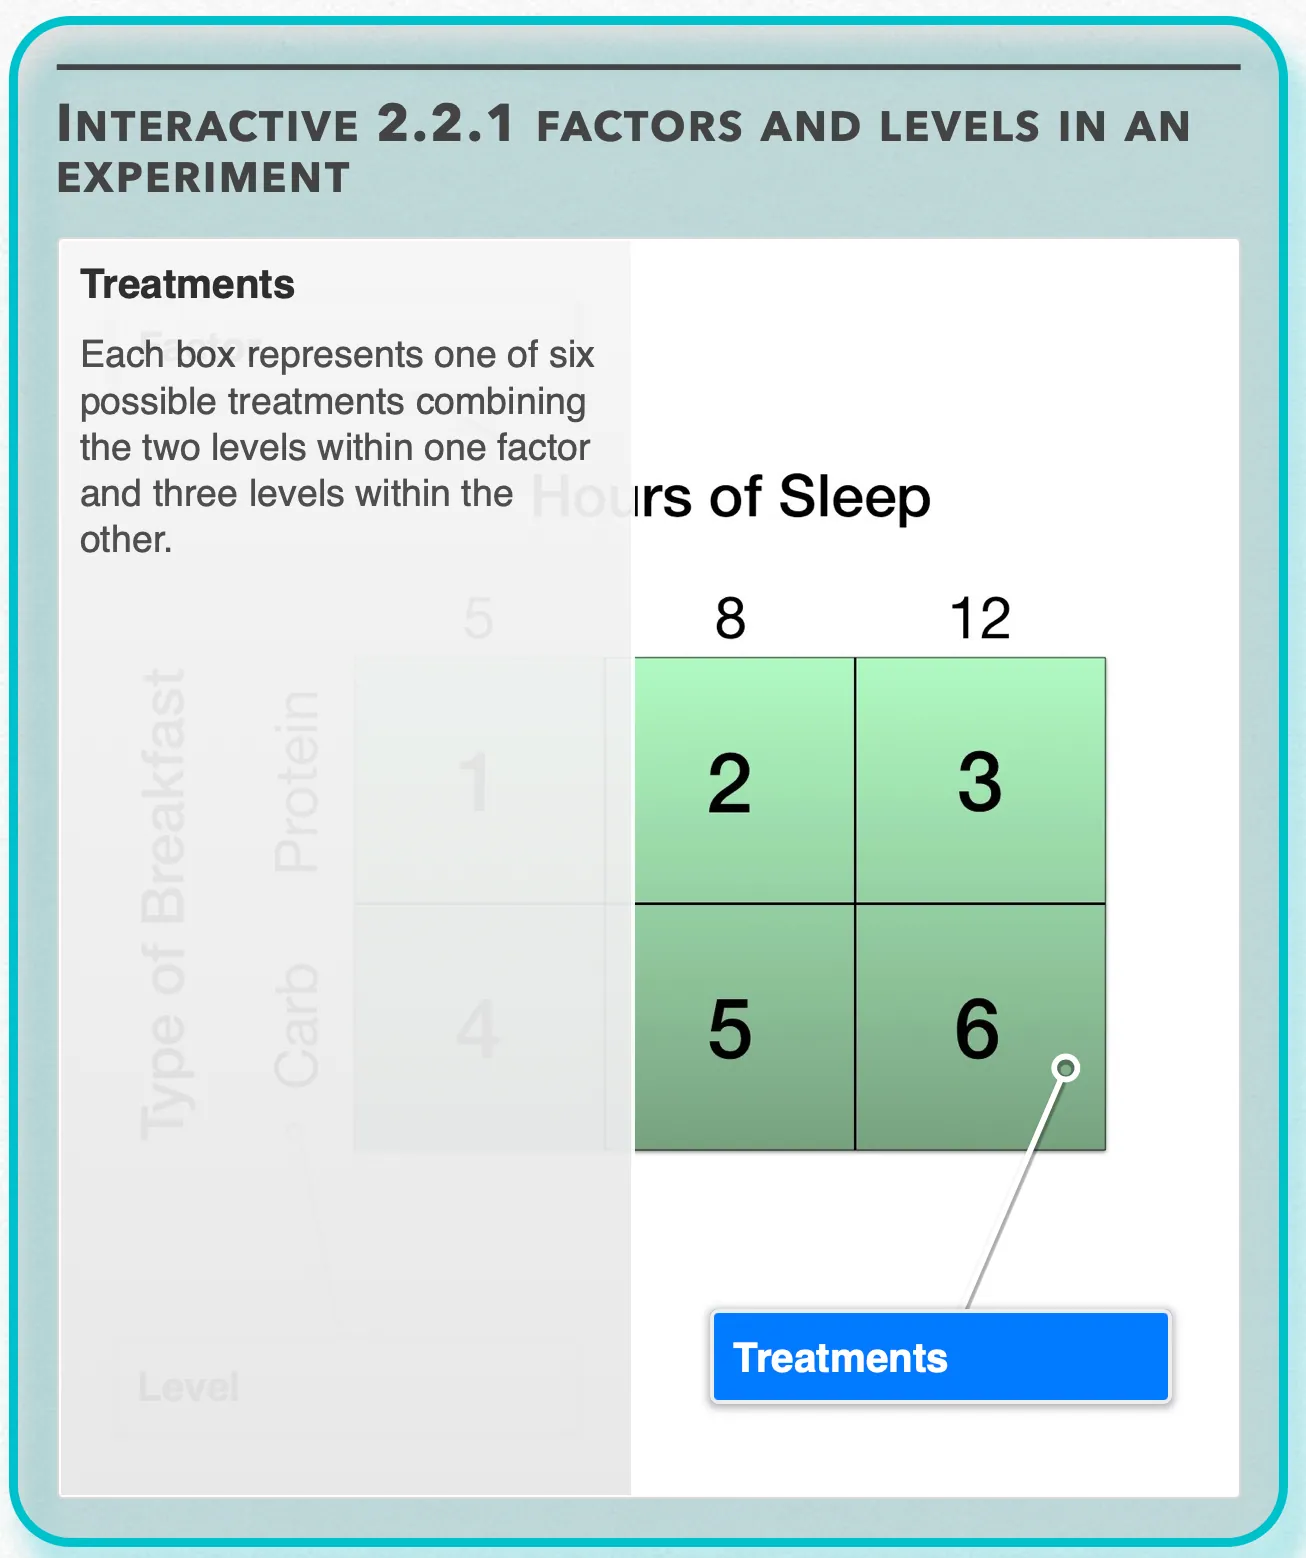
Treatments — Each box represents one of six possible treatments combining the two levels within one factor and three levels within the other. Open full-size image S0163
Capture provenance
Filename capture times, with no recorded timezone. Frames above follow the original gallery positions.
- · S0160 · displayed frame 1
Screenshot 2026-10-05 at 3.47.56 PM.png - · S0161 · displayed frame 2
Screenshot 2026-10-05 at 3.48.01 PM.png - · S0162 · displayed frame 3
Screenshot 2026-10-05 at 3.48.07 PM.png - · S0163 · displayed frame 4
Screenshot 2026-10-05 at 3.48.12 PM.png
| Type of Breakfast / Hours of Sleep | 5 | 8 | 12 |
|---|---|---|---|
| Protein | Treatment 1 | Treatment 2 | Treatment 3 |
| Carb | Treatment 4 | Treatment 5 | Treatment 6 |
Good Experimental Design
We’ve talked about experiments, but do we actually know what constitutes good experimental design? If an experiment is well-designed, then it has the following three characteristics:
- Control - The simplest type of control is comparison, or ensuring that the only difference between two or more groups is the treatment being imposed. This balances out the effects of the independent variable being confounded with the effects of the lurking variable. Sometimes this means adding a control group, a baseline by which to compare the treatments. The control group usually gets the inactive treatment. However, the control group can also be receiving a treatment that has been proven to work in the past, such as a placebo.
- Random Assignment - Randomly assigning subjects to treatments can also eliminate lurking variables that we haven’t thought of or can’t easily control. It ensures that the only difference between groups is chance variation. Control and randomization work together to prevent any bias in our experiments.
- Replication – When we use enough experimental units in our experiment, we greatly reduce chance variation within our groups so we are better able to detect differences between our treatments.
There are other ways to prevent bias and confounding. These include:
Blinding - Single-blind experiments are when one party knows which treatment each group is receiving (usually the doctor or researcher). Double-blind experiments are when neither party knows. Experiments should have at least single blinding, but it’s important to keep in mind that doctors and researchers might react differently to patients when they know which group is getting which treatment (like paying less attention to individuals in the control group because they already know if the treatment works or not).
Placebos – Giving a placebo, or fake treatment, to a control group can help prevent confounding due to the placebo effect, a psychological effect where individuals show a positive physical response to the treatment because of a believe that the treatment works.
Types of Experimental Designs
One more concept we must cover is the types of designs one can choose from when setting up an experiment, and when to use each one:
- Completely Randomized Design – When a completely randomized design has been implemented, it means that the experimental units have been randomly assigned to groups at the start of the experiment. Randomization will help balance the effects of the lurking variables.
- Blocked Design – Researchers implement a blocked design when they notice a lurking variable that could make it difficult to detect a difference between treatments, even when experimental units are randomly assigned to groups.
- Matched Pairs Design – A subset of the blocked design. It is implemented when differences between treatments can be hard to detect with either a completely randomized or a blocked design proper. Both treatments are assigned in a randomly determined order to a single experimental unit, or each treatment is assigned a pair of two similar experimental units.
Imagine the following scenarios. Which experimental design should be implemented for each one?
- An online review site compares two selected brands of stock-picking software to see if either one is more effective than using “intuition” alone.
- A university lets students pick between a traditionally-taught College Algebra course and an online College Algebra course to figure out which method is more effective.
- A drug company administers a pill designed to enhance mental acuity to a group of randomly selected people to see if it actually works.
- A tutoring company wants to know which special, sense-based learning technique they have developed is most effective. They consider that males and females might respond to each technique differently).
- A biotech lab has developed a patch designed to end migraines faster than aspirin. They consider that the causes and characteristics of migraines are highly varied between each individual.
Interactive 2.2.2 is based on the first scenario and illustrates the importance of taking lurking variables into account when choosing an experimental design and setting up your experiment Although it is quite comprehensive, it will help you better understand similar graphs in Gallery 2.2.1 also based on the aforementioned scenarios. Gallery 2.2.2 (yes, also based on the scenarios) will also help you understand the general steps for the different types of experimental design.
Interactive 2.2.2 The Importance of Eliminating Lurking Variables
Frame 1 of 5
Revenue is compared for the No Software Group, Software A Group, and Software B Group. Each bar is separated into Method Type and Market Strength. Callouts: Incomplete Conclusions, Lurking Variables, Control Group Effect, Lurking Variable Eliminated. Open full-size image S0166Frame 2 of 5
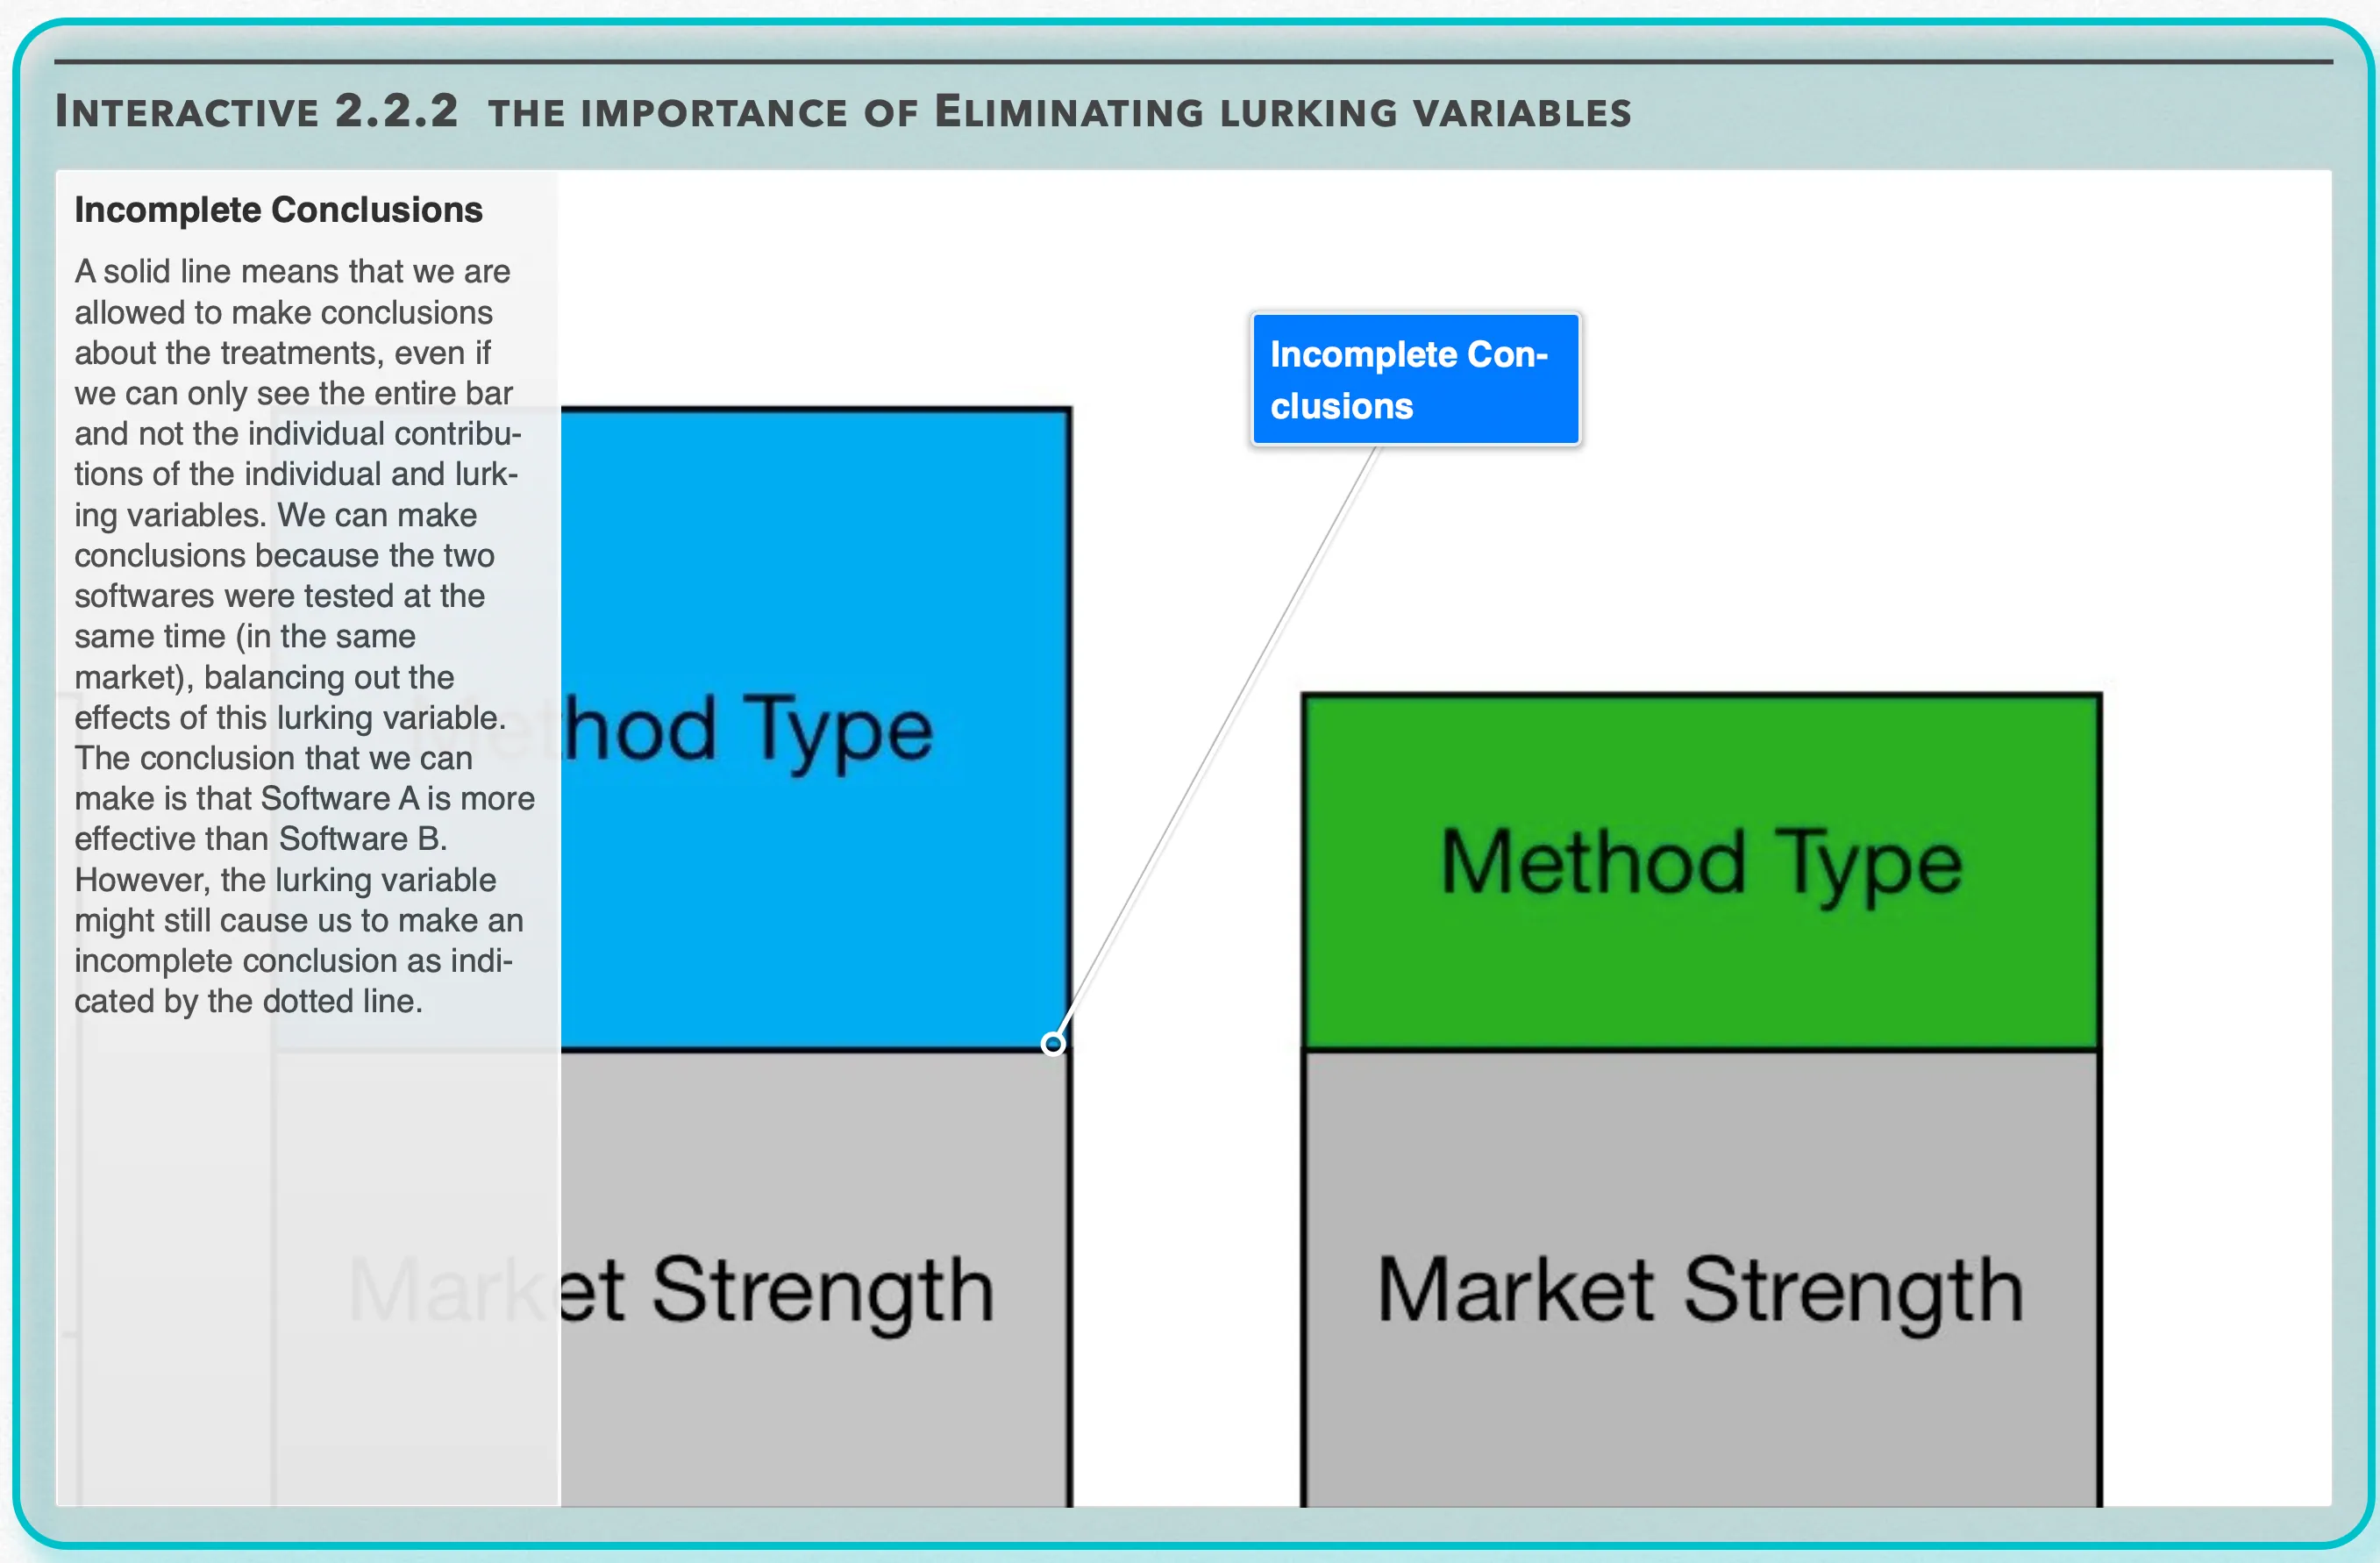
Incomplete Conclusions — A solid line means that we are allowed to make conclusions about the treatments, even if we can only see the entire bar and not the individual contributions of the individual and lurking variables. We can make conclusions because the two softwares were tested at the same time (in the same market), balancing out the effects of this lurking variable. The conclusion that we can make is that Software A is more effective than Software B. However, the lurking variable might still cause us to make an incomplete conclusion as indicated by the dotted line. Open full-size image S0167Frame 3 of 5
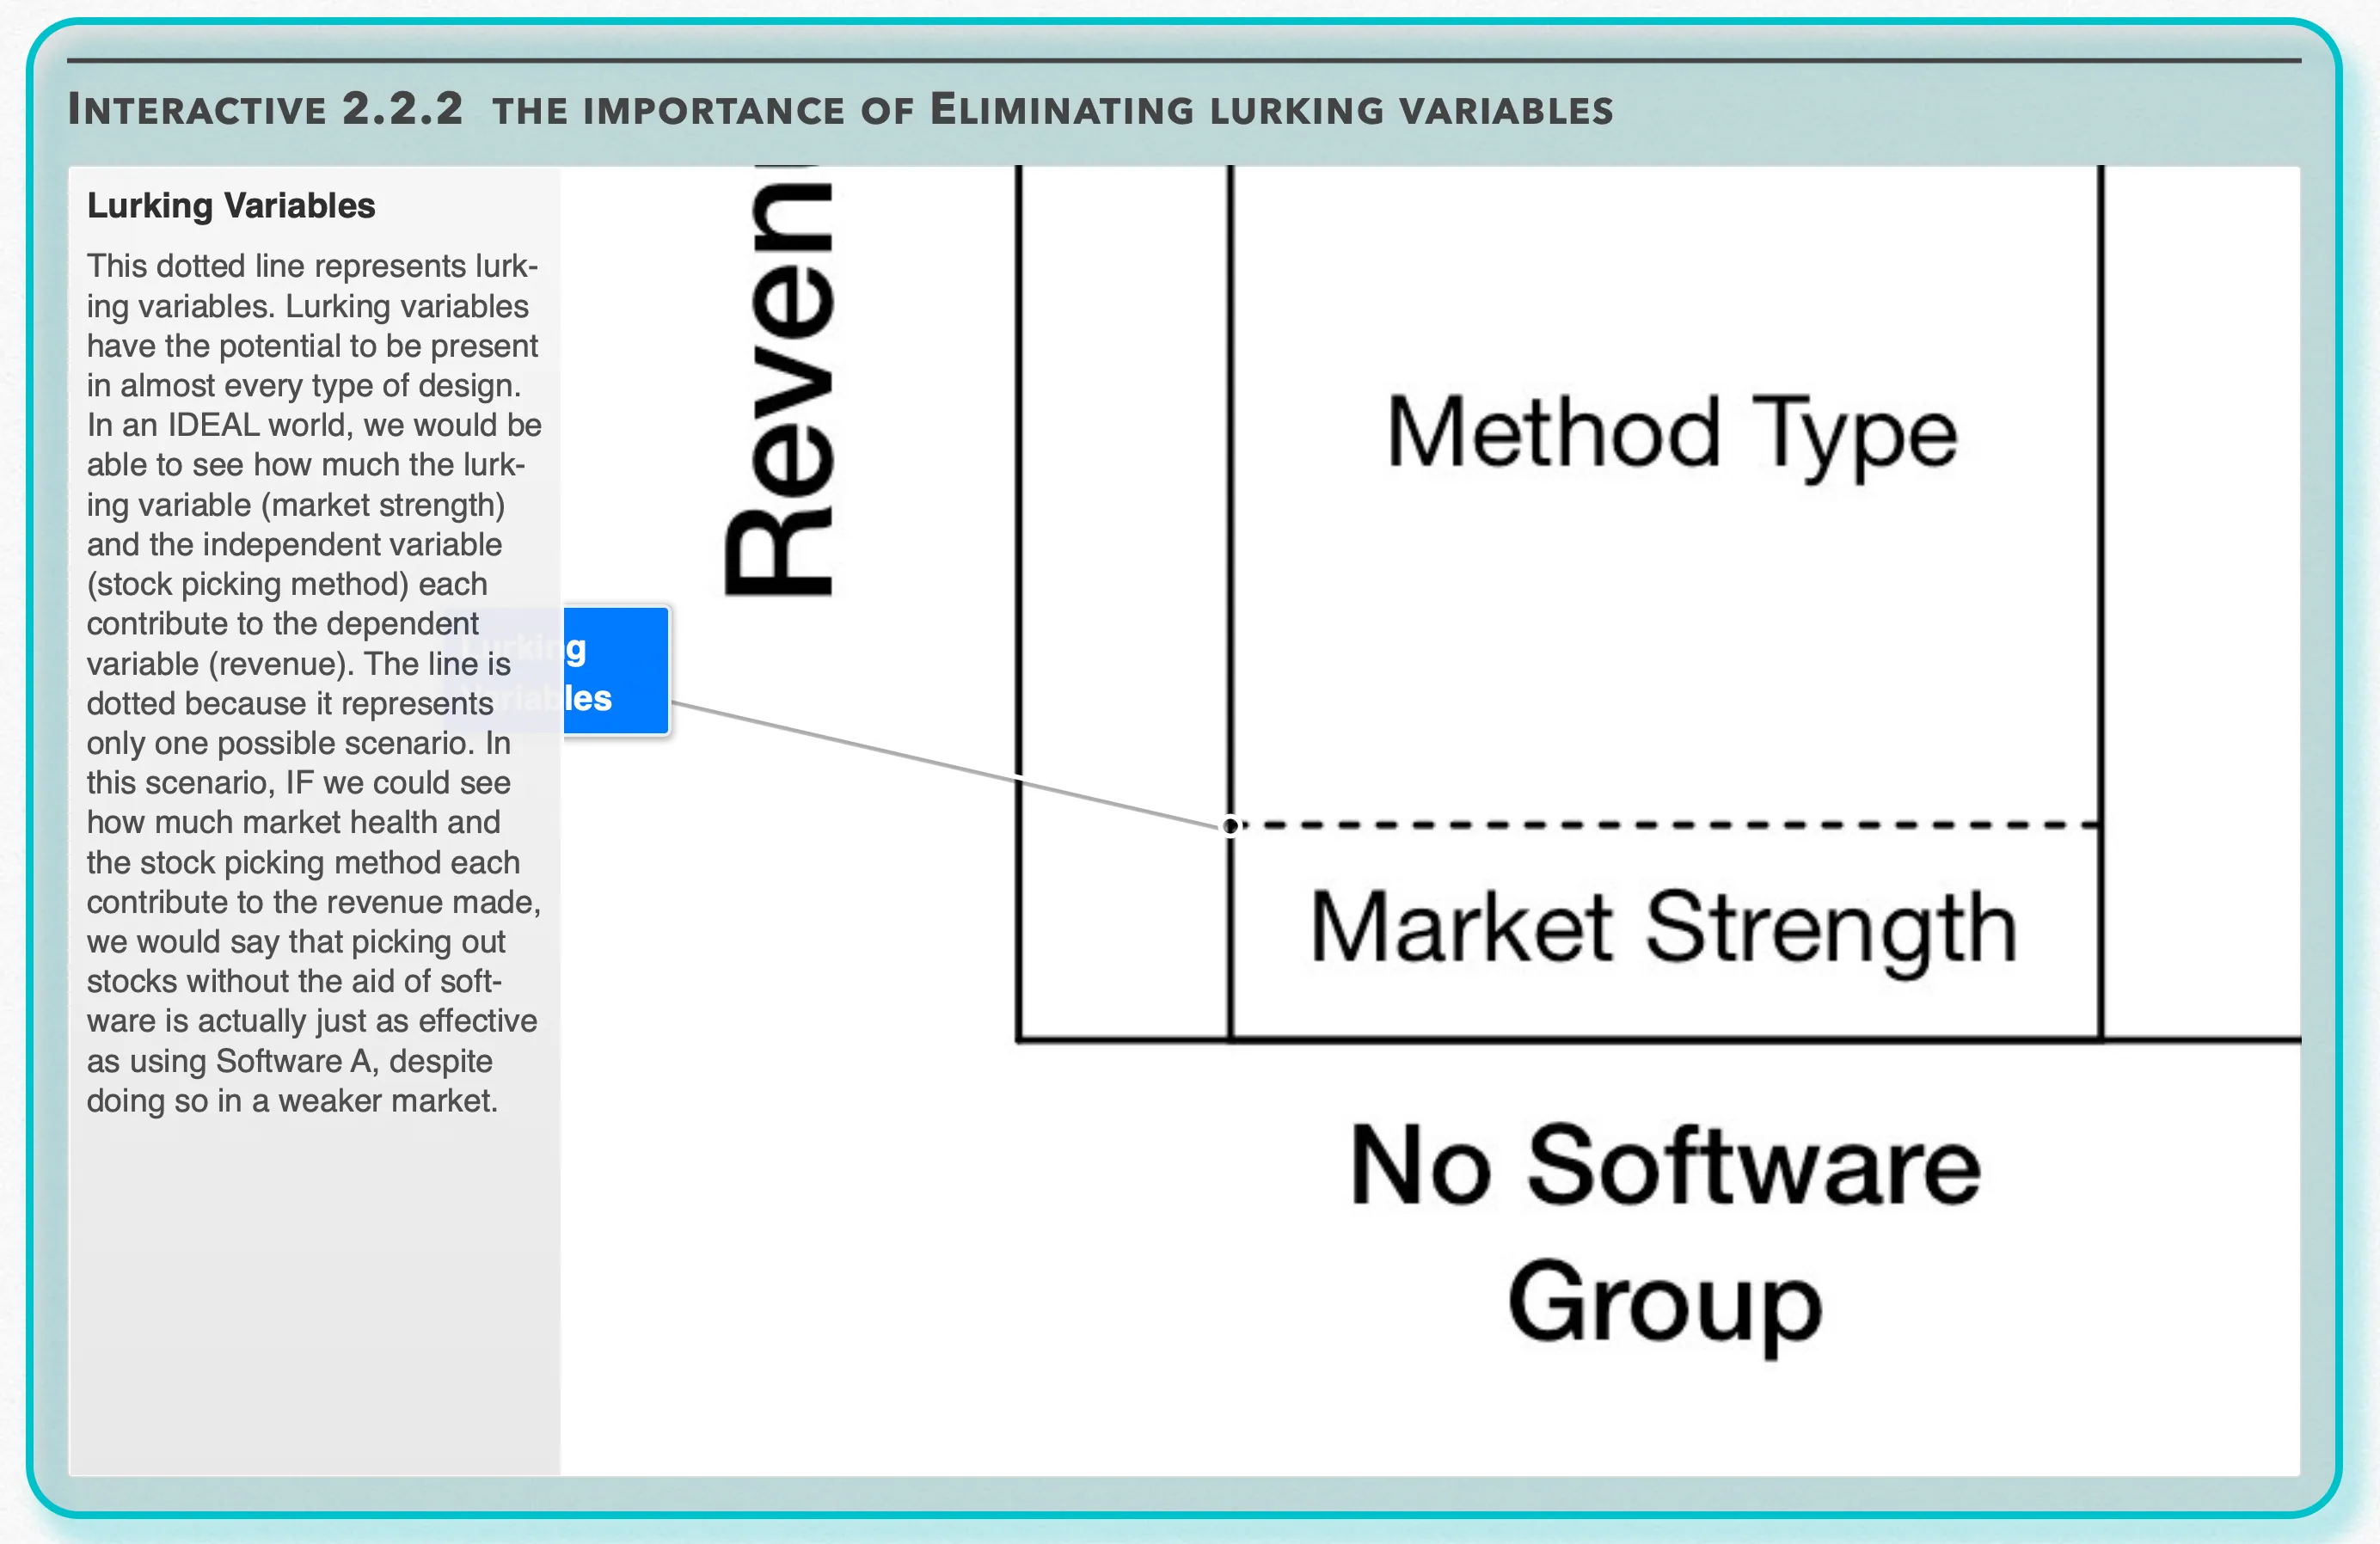
Lurking Variables — This dotted line represents lurking variables. Lurking variables have the potential to be present in almost every type of design. In an IDEAL world, we would be able to see how much the lurking variable (market strength) and the independent variable (stock picking method) each contribute to the dependent variable (revenue). The line is dotted because it represents only one possible scenario. In this scenario, IF we could see how much market health and the stock picking method each contribute to the revenue made, we would say that picking out stocks without the aid of software is actually just as effective as using Software A, despite doing so in a weaker market. Open full-size image S0168Frame 4 of 5
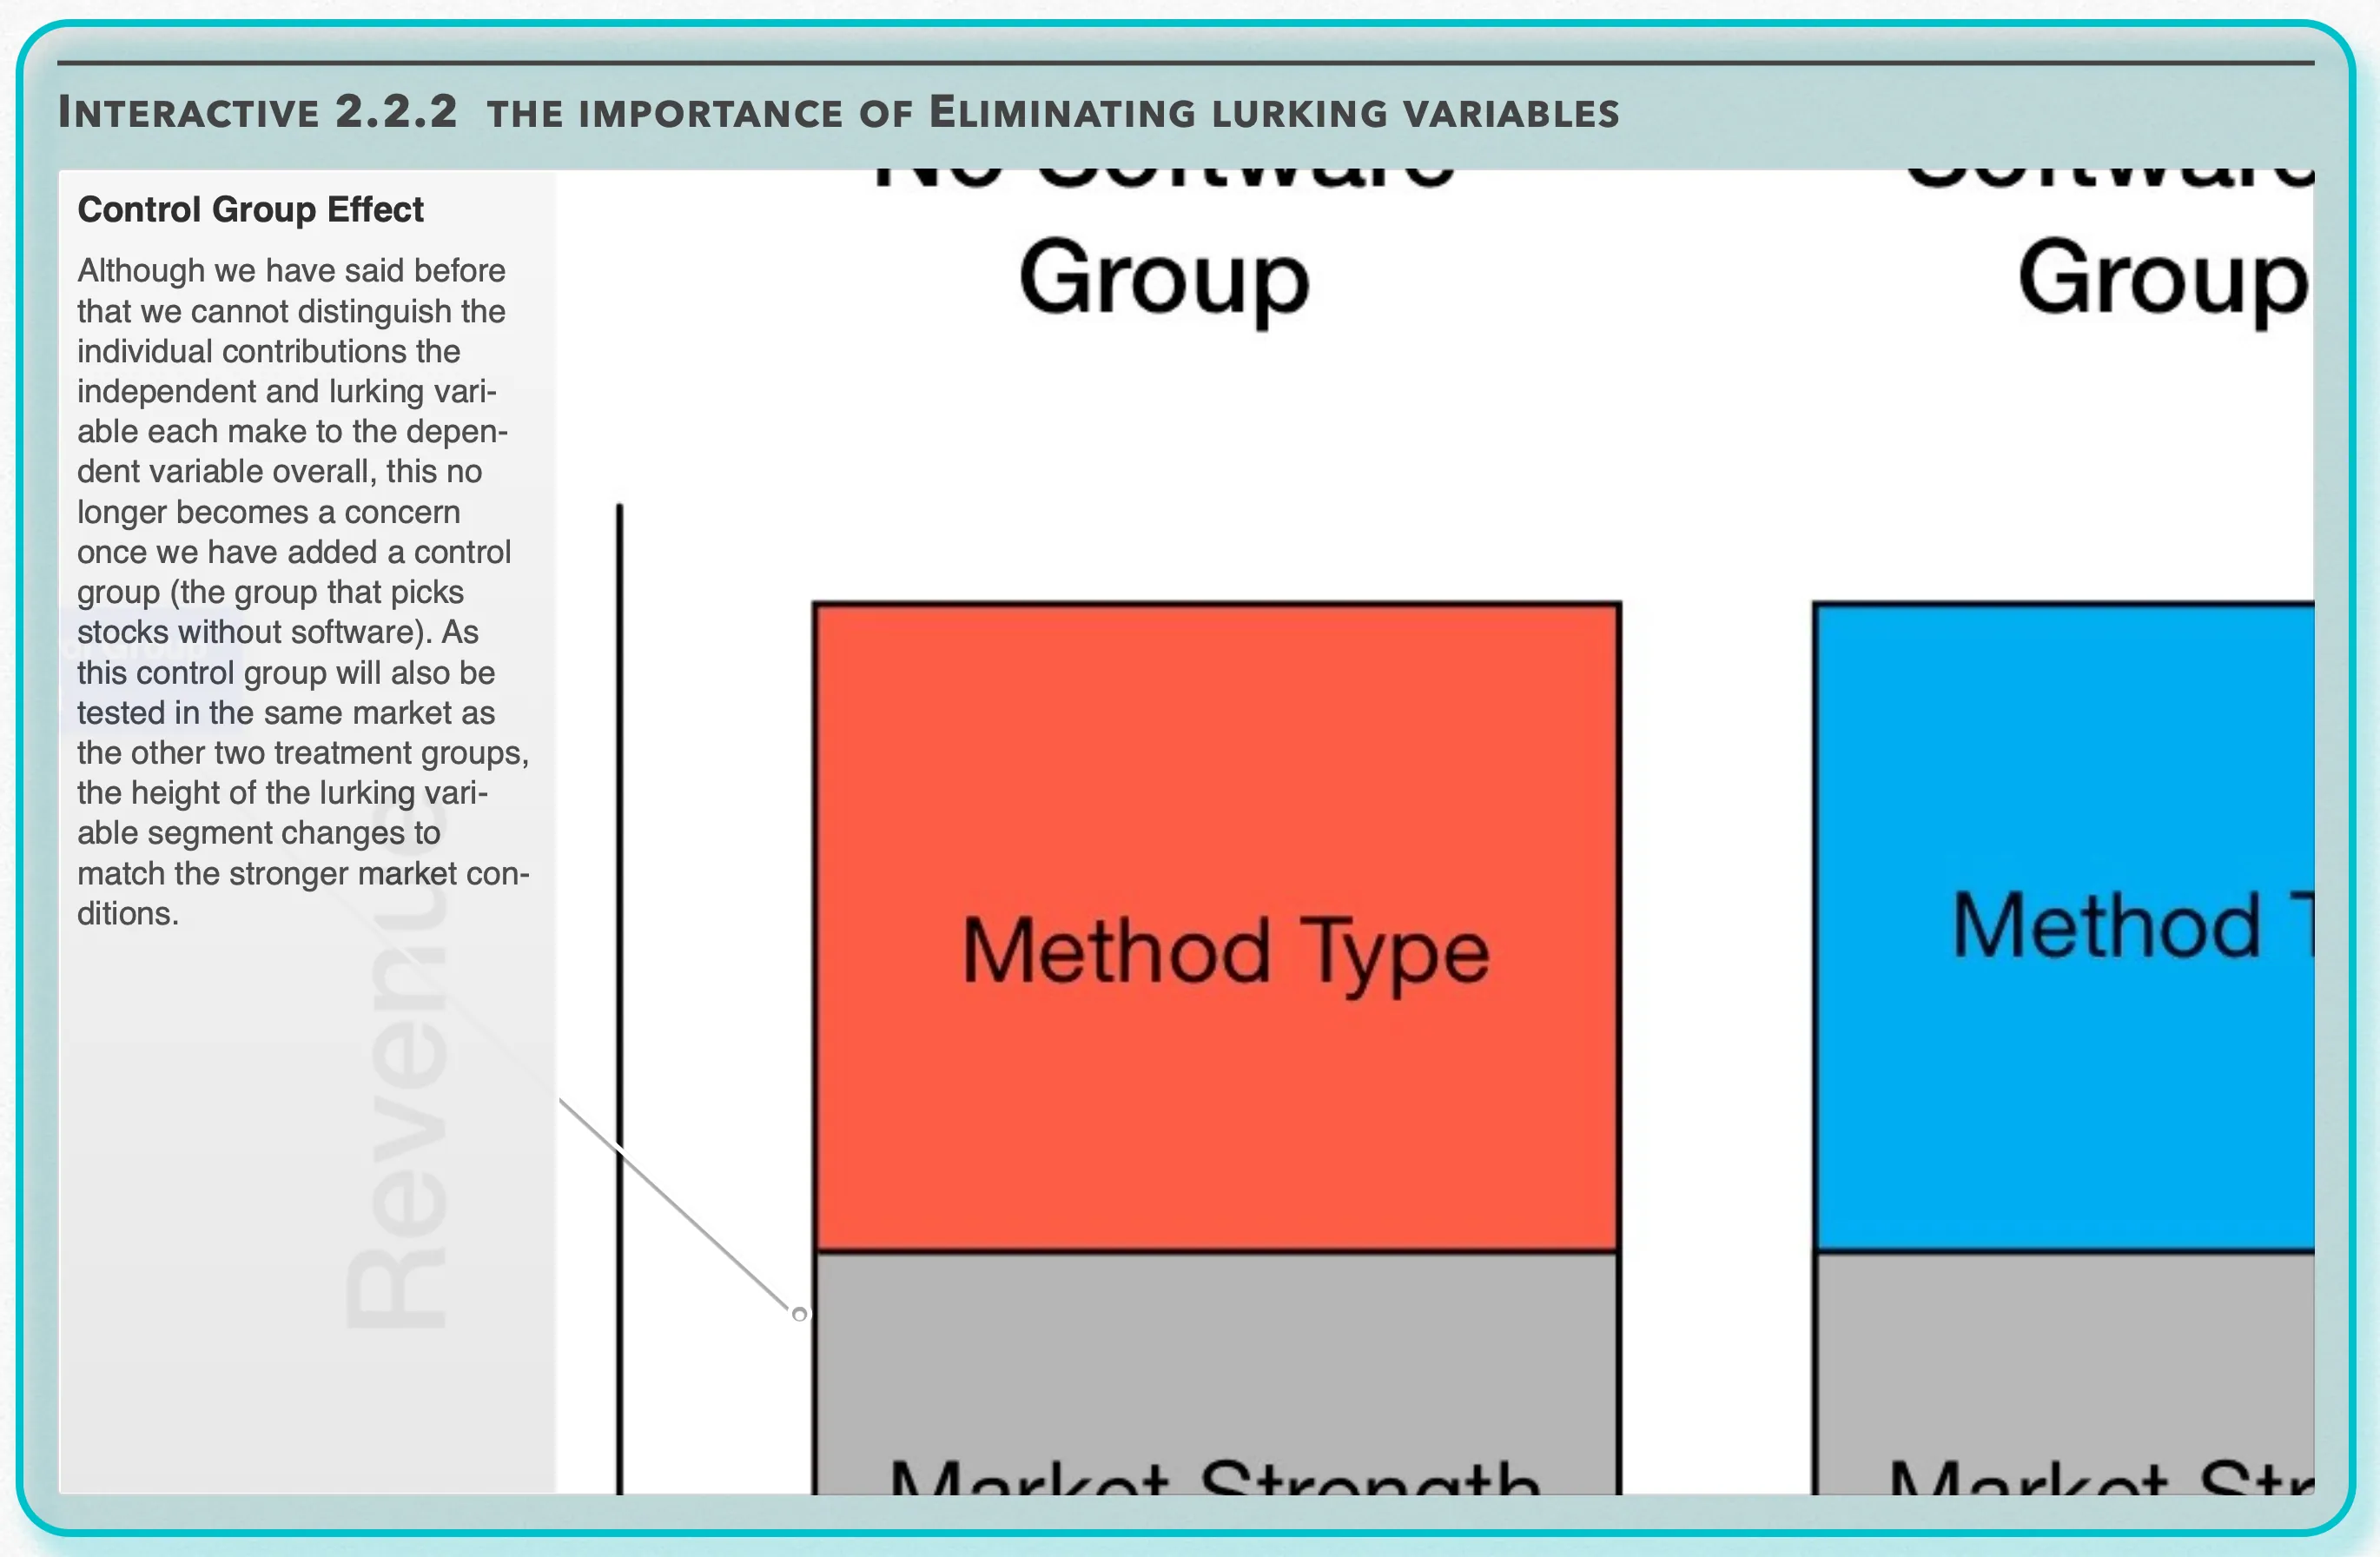
Control Group Effect — Although we have said before that we cannot distinguish the individual contributions the independent and lurking variable each make to the dependent variable overall, this no longer becomes a concern once we have added a control group (the group that picks stocks without software). As this control group will also be tested in the same market as the other two treatment groups, the height of the lurking variable segment changes to match the stronger market conditions. Open full-size image S0169Frame 5 of 5
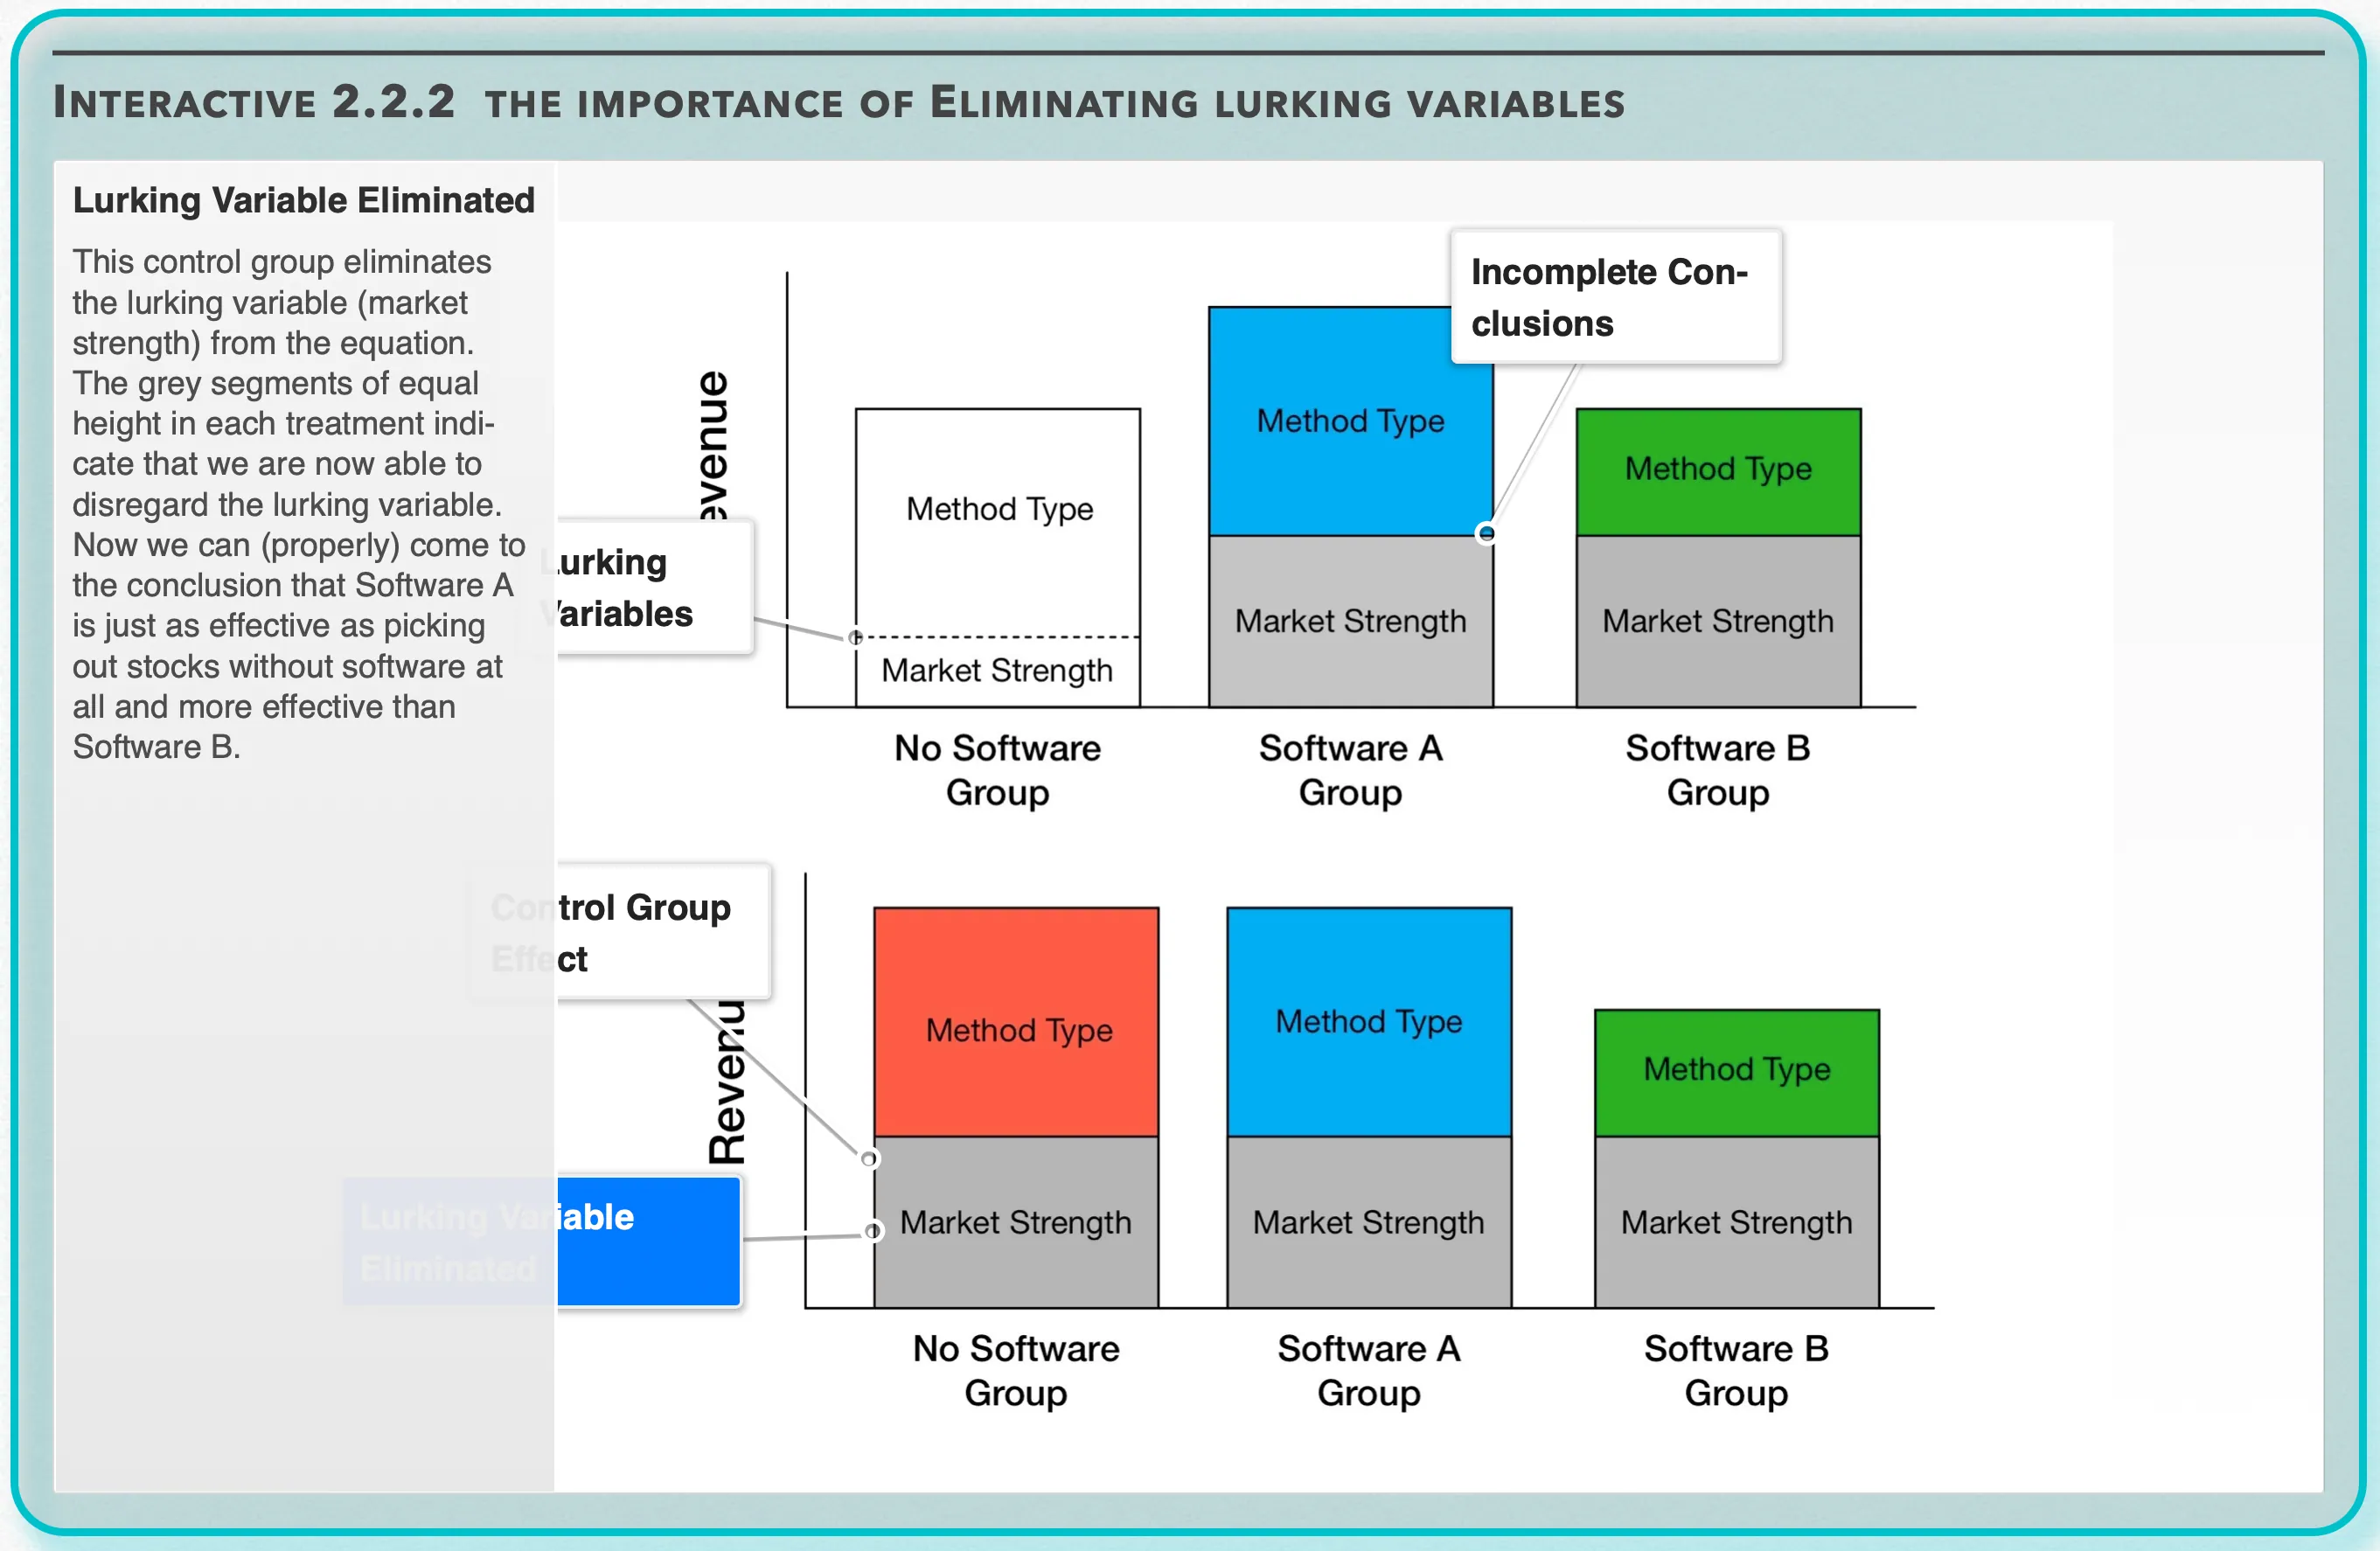
Lurking Variable Eliminated — This control group eliminates the lurking variable (market strength) from the equation. The grey segments of equal height in each treatment indicate that we are now able to disregard the lurking variable. Now we can (properly) come to the conclusion that Software A is just as effective as picking out stocks without software at all and more effective than Software B. Open full-size image S0170
Capture provenance
Filename capture times, with no recorded timezone. Frames above follow the original gallery positions.
- · S0166 · displayed frame 1
Screenshot 2026-10-05 at 3.48.19 PM.png - · S0167 · displayed frame 2
Screenshot 2026-10-05 at 3.48.26 PM.png - · S0168 · displayed frame 3
Screenshot 2026-10-05 at 3.48.32 PM.png - · S0169 · displayed frame 4
Screenshot 2026-10-05 at 3.48.38 PM.png - · S0170 · displayed frame 5
Screenshot 2026-10-05 at 3.48.57 PM.png
Gallery 2.2.1 More Examples of Eliminating Lurking Variables
Frame 1 of 6
The importance of Randomization in experimental design: in this scenario, if we allow students to pick which group to participate in and the more hard-working students pick the traditional class, then the traditional classroom is going to appear to be more effective than it really is, even if it is still more effective than the online class. Open full-size image S0171Frame 2 of 6
Randomly assigning students to the class groups will ensure the effects of the lurking variable, time/effort, are minimized. Notice when we do this, the overall performance of the traditional group relative to the online group decreases. The traditional classroom is less effective than it appeared to be initially. Open full-size image S0172Frame 3 of 6
The importance of Control in experimental design: without a control group to take a placebo, the pill may seem more effective than it really is because the “boosted” effect of simply taking the pill (placebo effect) contributing to the overall response. Open full-size image S0173Frame 4 of 6
Adding a control group and assigning the subjects in that group to take a placebo will ensure effects of the lurking variable, simply taking the pill (placebo effect) are minimized. When we do this, the effect from simply taking the pill can be separated from the effect of the actual treatment. Open full-size image S0174Frame 5 of 6
The importance of Blocking when necessary in experimental design: if males and females are more responsive to specific learning methods, then without blocking, the true effectiveness of each learning method can’t be measured because of the lurking variable of gender. Open full-size image S0175Frame 6 of 6
Blocking males and females into different groups will ensure the effects of the lurking variable, gender, are minimized, making it easier to detect differences in the treatments. For instance, we can now see that males are more effective visual learners, but females are more effective olfactory learners. Open full-size image S0176
Capture provenance
Filename capture times, with no recorded timezone. Frames above follow the original gallery positions.
- · S0171 · displayed frame 1
Screenshot 2026-10-05 at 3.49.01 PM.png - · S0172 · displayed frame 2
Screenshot 2026-10-05 at 3.49.06 PM.png - · S0173 · displayed frame 3
Screenshot 2026-10-05 at 3.49.12 PM.png - · S0174 · displayed frame 4
Screenshot 2026-10-05 at 3.49.16 PM.png - · S0175 · displayed frame 5
Screenshot 2026-10-05 at 3.49.21 PM.png - · S0176 · displayed frame 6
Screenshot 2026-10-05 at 3.49.26 PM.png
Gallery 2.2.2 Steps in Different Types of Experimental Designs
Frame 1 of 3
The traditional versus online course example will be constructed using a completely randomized design. 800 students are randomly assigned to two treatments: either the traditional course or the online course. Then the effectiveness of each treatment are compared. Open full-size image S0171Frame 2 of 3
The learning techniques example will be constructed using a blocked design because it was mentioned that men and women learn differently. If the experiment has 1200 subjects (615 men and 585 women) then men and women will be blocked into different groups before being randomly assigned to the visual task, auditory task, or olfactory task. Then the effectiveness of the treatments within each block are compared Open full-size image S0177Frame 3 of 3
The migraine sufferers example will be constructed using a matched pairs design because it was mentioned that the causes and characteristics of migraines are highly varied between each individual. If the experiment has 1500 subjects then each subject will be randomly assigned to either the aspirin or the patch. Then they take the treatment that they initially weren’t randomly assigned. Then the effectiveness of the treatments are compared 1500 times. Open full-size image S0178
Capture provenance
Filename capture times, with no recorded timezone. Frames above follow the original gallery positions.
- · S0171 · displayed frame 1
Screenshot 2026-10-05 at 3.49.01 PM.png - · S0177 · displayed frame 2
Screenshot 2026-10-05 at 3.49.31 PM.png - · S0178 · displayed frame 3
Screenshot 2026-10-05 at 3.49.36 PM.png
The source’s design-flow labels and counts are transcribed here:
| Frame | Starting group | Random assignment | Treatments / comparison |
|---|---|---|---|
| 1 | 800 students | Upper: Group 1, 400 students. Lower: Group 1, 400 students. | Treatment 1 (Traditional course); Treatment 2 (Online course); Compare performance |
| 2 | 1200 Paid subscribers to Tutoring Company: Men (), Women () | Men: Group 1, Group 2, Group 3, each . Women: Group 1, Group 2, Group 3, each . | Visual Task; Auditory Task; Olfactory Task; Compare performances within each block |
| 3 | Migrane Sufferers (): Subject 1, Subject 2, Subject 3, …, Subject 1500 | Random Assignment for each subject | Subjects 1 and 3: Aspirin → Patch. Subjects 2 and 1500: Patch → Aspirin. Compare Treatments in each row. |
Example 2.2.1
Example 2.2.1 — Recorded answer
a) Random Assignment: The members that selected Automatic Athlete because it was displayed more prominently might lead the researchers to believe their brand is more effective than it really is. Also, the members that came first might be more health-conscious than their later-day counterparts, which could contribute more to their muscle gain than just the pill alone. Random assignment would make sure that the effects of this lurking variable, overall health, would be spread out relatively evenly between the two groups.
Control: The scientists not only wanted to know that their brand was more effective than the competition, but that it was more effective than just working out alone. They can’t do this without a control group, a baseline to compare the other two treatment groups to. They would want to give the control group a placebo rather than nothing at all because they don’t know how much (1) the effect of the brand and (2) the psychological effect of simply taking pills each individually contributes to the gain in muscle mass. In other words, the effects are confounded.
Blinding: The gym members knew which treatment they were getting, and so did the scientists. Now that we have introduced a placebo group, we don’t want any treatment group knowing whether or not they got an active treatment. If there isn’t going to be a lot of scientist-patient interaction, then single-blind might be appropriate. Otherwise, they should go with double-blind.
Blocking: It was stated earlier that men and women are suspected to have different reactions to each of the brands, but the scientists chose not to react upon it. This could make it more difficult to distinguish a difference between the effects of the two treatments. For instance, perhaps females gain more on Automatic Athlete and males gain more on Beefy Brawn. This could be solved by a blocked design, where males and females are purposely separated into two groups, with the individuals in each groups being randomly assigned to the placebo, Automatic Athlete, or Beefy Brawn treatments.
b) Replication: A grand total of 47 subjects seems like a rather small number, especially for a product of research that likely had an investment of millions of dollars put into it. If the scientists could gather hundreds, or preferably even thousands of subjects for each group, then the effects of the pills could be distinguished from chance variation between the groups.
Pop Quiz 2.2.1
Glossary and deeper reading · 13 refreshers
These editorial refreshers supplement the reading. Definitions and examples are added guidance; original source wording and recorded answers remain in their original context.
-
Observational study
An observational study measures individuals without assigning the treatments or conditions being compared. It can reveal associations, but confounding can prevent a causal conclusion. For example, recording students’ existing sleep habits and scores is observational when researchers do not assign sleep schedules.
-
Treatment
A treatment is a specific condition imposed on an experimental unit. In a multifactor experiment, a treatment is a combination of factor levels. For example, low fertilizer with eight hours of light is one treatment combination.
-
Explanatory variable
An explanatory variable is used to predict or explain variation in a response variable. In an experiment, researchers deliberately assign values or treatments related to an explanatory variable. For example, assigned study time could be an explanatory variable when test score is the response.
Read more: Explanatory variable in the captured Statistics reading →
-
Experimental factor
A factor is an explanatory variable deliberately varied in an experiment. Each assigned setting of that factor is called a level. For example, fertilizer type is a factor with levels corresponding to the fertilizer choices.
-
Confounding
Confounding occurs when the effects of different variables cannot be distinguished in the observed comparison. A potential explanation is that another variable is related to both the treatment or explanatory variable and the response. For example, comparing fertilizer A outdoors with fertilizer B indoors mixes fertilizer and growing-location effects.
-
Lurking variable
A lurking variable is an unmeasured or unaccounted-for variable that helps explain an observed relationship. It may create confounding when it is related to both variables being studied. For example, prior preparation might influence both time spent studying and test score.
-
Statistical bias
Statistical bias is a systematic tendency to favor some outcomes or miss a target value. For an estimator, bias is its long-run average estimate minus the parameter it estimates. For example, a survey that consistently misses evening workers may systematically misrepresent commuting patterns.
Read more: Statistical bias in the captured Statistics reading →
-
Replication
Replication uses multiple independent experimental units for each treatment. It helps estimate chance variation and increases the information available for comparing treatment responses. For example, assigning many independently treated plants to each fertilizer is replication, while repeatedly measuring one plant adds a different kind of information.
-
Experimental unit
An experimental unit is the smallest unit independently assigned a treatment. A human experimental unit is often called a subject or participant. For example, if fertilizer is assigned to an entire planter, the planter rather than each leaf is the experimental unit.
-
Blinding
Blinding keeps specified participants or study personnel unaware of assigned treatments. The study should state who is blinded because labels such as single-blind and double-blind can be used differently. For example, both participants and outcome assessors can be kept unaware of which pill was assigned.
-
Control group
A control group supplies a comparison for evaluating an experimental treatment. It may receive a placebo, no active treatment, or an established treatment, depending on the study’s design. For example, a fertilizer experiment may compare a new fertilizer with the usual fertilizer rather than with no fertilizer.
-
Placebo
A placebo resembles an active treatment but lacks the active intervention under study. It helps provide a comparison for effects associated with receiving treatment and expectations. For example, an inactive pill can be made to look like the experimental pill.
-
Placebo effect
A placebo effect is a response associated with expectations or the experience of receiving a treatment. Observed change in a placebo group can also include natural recovery or other influences, so it is not all automatically a placebo effect. For example, reported discomfort may change after a participant receives an inactive pill.